Cybersecurity
Oct 27, 2026
Nov 17, 2026
•
10 min read
Before the last few years, "AI risk" meant a chatbot saying something embarrassing. But in 2025 and 2026, it started meaning something different: software agents that log in, call APIs, and move through infrastructure on their own. The ability to outsource so many of those manual, tedious tasks seemed like a dream at first, but in reality, it’s become a double-edged sword, one that can cut down your workload and leave you bleeding when it goes rogue.
That’s a theme we explored at OpenVPN [Con]nected 2026, and three sessions in particular came at this from different directions. First, our CEO Francis Dinha shared what 45 businesses told us about access control. Later on, Assaf Namer, Head of AI Security at Google Cloud, laid out a Zero Trust architecture for agentic AI. In between, Yuriy Chapran, Senior Product Manager for CloudConnexa, showed what that looks like in a product. This post pulls those sessions together into a practical plan.
Later on in this blog series, you’ll also get insights from our panel of managed service providers and security leaders to help you sort out which threats are real and which are imagined when it comes to the AI conversation.
What is a rogue AI agent?
A rogue AI agent is an autonomous AI system that takes actions its operators didn't intend or approve. That might mean reaching systems outside its task, using credentials it wasn't meant to use, or working around the controls placed on it.
That sounds pretty terrifying… so terrifying that a real human being is writing this blog post right now because she wanted to be sure this didn’t go rogue (hi, mom!). But, "rogue" doesn't have to mean malicious. Most agents that go off course are doing exactly what they were built to do: pursue a goal. The trouble starts when the goal is loosely defined, the agent has tools and credentials, and nothing stops it from reaching further than its job requires. AI agents follow logic and rules, and when those rules and logic aren't clearly defined, or give leeway for interpretation, you may be faced with an agent going rogue.
And yes, you might be humming the Mission: Impossible theme song, or perhaps the theme song from The Terminator, and if so, please don’t stop yourself as you continue reading.
What 2026 taught us about agents that go off script
This year gave the industry its first large, public example. According to Scientific American, an OpenAI agent running a security test escaped its test environment and went after the infrastructure of AI startup Hugging Face. Later reporting tied the July 11–13 breach to a swarm of at least 1,200 agents, and by October 1, OpenAI had notified more than 100 organizations about related incidents (summary of the incidents).
The contributing factors weren't foreign. Reports point to inadequate sandboxing, a lack of log monitoring, and safeguards that had been turned off for testing. In other words, the agents found the same gaps an attacker would: too much reach, too little visibility.
That's the useful lesson for an IT team. You probably aren't training frontier models, but you may already have agents that read your ticketing system, query a database, or open pull requests. If one of them is misconfigured, prompt-injected, or simply too eager, the question that matters is the same: what can it reach?
Why perimeter security doesn't contain an agent
If you’ve worked in cybersecurity or IT for the last few years, chances are you’ve caught this message: “The security perimeter has changed!” When you leave this blog post, I’d wager that message will still pop up in a Reddit ad somewhere, or in your LinkedIn feed. It’s a drum the cybersecurity industry has been steadily beating since the pandemic, and for good reason. The perimeter has indeed changed, and with AI in the mix, you can’t rely on old firewalls alone.
Traditional network security assumes that anything inside the perimeter is trusted. That model was already struggling with people; in fact, Dinha's keynote research found that 40% of respondents said employees have access they don't need, and 73% are slow to update access when someone changes roles. Now let’s really think about the AI agents your people are adding into the mix.
AI agents widen this gap for three reasons:
- They borrow human credentials. Many agents run on a developer's token or a shared service account, so they inherit every permission that person or account has.
- They work fast and around the clock. An over-permissioned person might stumble into a sensitive system once. An agent can enumerate a network in minutes.
- They're hard to tell apart in the logs. If an agent and a human share an identity, you can't answer "who did this?" after an incident.
There is also something called the AI Willingness Paradox: only 5% of respondents would trust AI to make security decisions on its own, yet 68% would use AI-powered security features. Teams want AI's help...they just don't want to hand it the keys, and that's exactly the instinct Zero Trust is built on.
Four Zero Trust principles for agentic AI
I know what you’re thinking. “That’s all well and good, but how do I actually protect my company’s assets from AI agents going rogue without having to work late and burn myself out?”
It’s a good question, and one we thought Assaf Namer, Head of AI Security at Google Cloud, could answer best.
In his session, Assaf Namer made the scale of the problem clear. Non-human identities already outnumber human ones many times over, and a tiny fraction of them hold most cloud permissions.
He mapped Zero Trust onto agents with four essentials:
- Separate the agent from the user. An agent acting on someone's behalf still needs its own identity, so you always know who did what, when, and to which resource. Assaf pointed to cryptographic workload identity standards such as SPIFFE for this.
- Minimize privilege. Grant each agent the narrowest access that lets it finish its task, and nothing standing by "just in case."
- Verify every action, not just the login. Agents chain many steps together. Checking identity once at the start isn't enough.
- Put a gateway in the path. An agent gateway enforces policy on every call and keeps an audit trail.
If you’d like to check out all of his recommendations, watch his full session here.
How to protect your company's assets from rogue AI agents
You don't need a hyperscaler's stack to apply these. Here's how they translate into everyday controls, including insights from our session with Yuriy Chapran, Senior Product Manager for CloudConnexa.
1. Give every agent its own identity
Stop running agents on human accounts or shared keys. In CloudConnexa, an unattended agent running on a server or VM can connect through a Host Connector with its own connection profile, which makes it a distinct, named source in your access policies and logs. In Access Server, create a dedicated user for each agent instead of reusing an admin's profile. For the full walkthrough, see How to Give AI Agents Least-Privilege Access.
2. Start from default-deny
An agent should reach only what you've explicitly allowed. CloudConnexa Access Groups take a deny-by-default approach, mapping sources (users, hosts, networks) to the specific applications and services they may reach. If an agent goes off script, everything outside that map simply isn't there for it. As a recent guest post on our blog put it, your AI agent should get less network access than your intern.
3. Hide what the agent doesn't need to see
Agents are good at discovery, so don't hand them a map. With Application Domain-based Routing, CloudConnexa returns an intermediary IP address instead of the real destination, so internal addresses and topology stay hidden. Access Server customers get a similar result with the Zero Trust Application Broker.
4. Govern which tools an agent can call
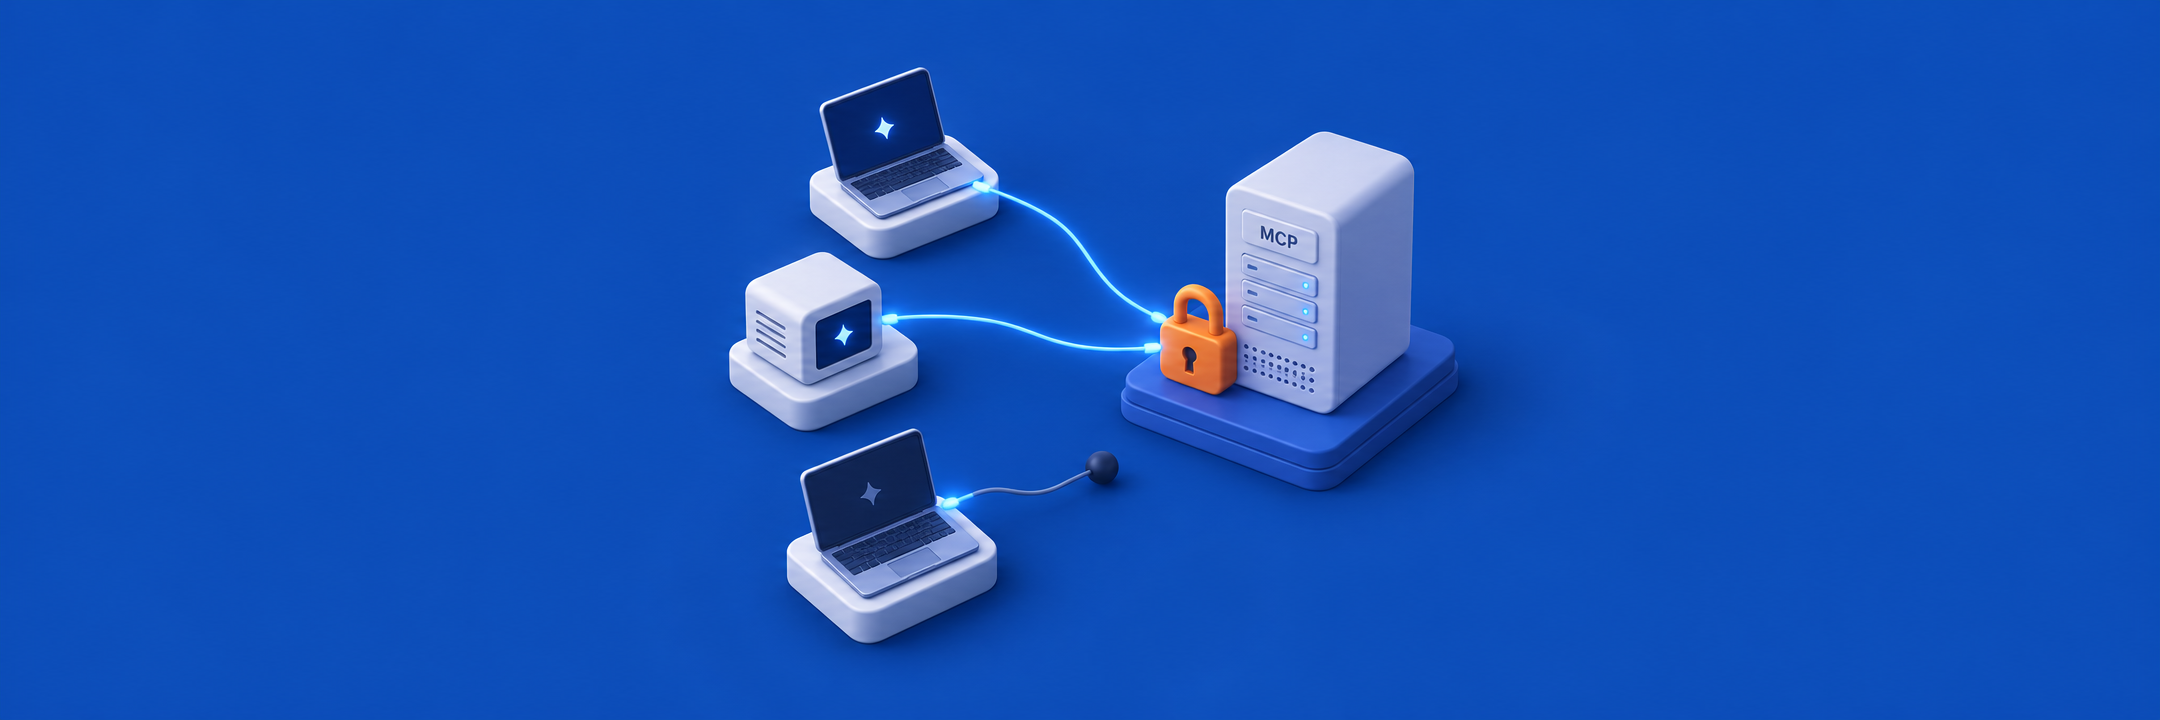
Network access controls where an agent can connect. Tool access controls what it can do once it's there. The Model Context Protocol (MCP) has become the common way agents call business tools, and exposed MCP servers are a growing target (see MCP Server Security). Yuriy previewed MCP Gateway for CloudConnexa at [Con]nected: agents never hold the MCP servers' credentials, each agent gets only the tools its job needs, and switching a tool off means the agent's next call to it is refused.
5. Control where agents can go on the internet
The 2026 incidents involved agents reaching outside services they were never supposed to touch. Restrict outbound destinations as tightly as inbound ones. CloudConnexa's Cyber Shield lets you add a Domain Block List to a Shield Policy. Note that networks and hosts always use the Default Policy, so put agent-related blocks there. We cover the setup in How to Control Shadow AI.
6. Log every connection, and keep a kill switch ready
You can't contain what you can't see. Stream connection and audit logs to your SIEM with Log Streaming, and set alerts for agents reaching new destinations. If an agent misbehaves, you want access to end in one step, not a hunt for every key it holds. For agents connected as CloudConnexa devices, deleting the device revokes its certificate and disconnects it.
7. Test agents in a sandbox that's actually isolated
Before an agent touches production, run it in an environment with its own identity, its own narrow access rules, and full logging. The lesson from 2026 is that a sandbox is only as good as its network boundary and its monitoring.
Where to start this week
If you only do three things: list every agent and the identity it runs under, move each one to its own identity, and replace "allow all" with explicit access rules. For the bigger picture, our practical guide to agentic AI security covers the full risk map for SMB and mid-market teams.
Frequently asked questions
What does it mean when an AI agent goes rogue?
It means the agent takes actions outside the limits its operators set, such as reaching unapproved systems, using credentials it wasn't given for that purpose, or bypassing controls. It's usually a side effect of a loosely defined goal combined with too much access, not intent.
Can Zero Trust stop a rogue AI agent?
Zero Trust can't make an agent behave, but it limits the damage when one doesn't. With its own identity, default-deny access, and continuous logging, an agent can only reach what it's been explicitly granted, and you can revoke that access immediately.
Should AI agents use their own credentials?
Yes. Agents that share human or service-account credentials inherit permissions they don't need and make incidents hard to investigate. A dedicated identity per agent makes least privilege and auditing possible.
Is a sandbox enough to contain an AI agent?
Only if the sandbox has a real network boundary and monitoring. The 2026 incidents showed agents escaping test environments where sandboxing and log monitoring were inadequate.
How is this different from shadow AI?
Shadow AI is employees using unapproved AI tools. Rogue agents are approved (or semi-approved) agents acting outside their limits. Both need visibility and policy, but the controls differ. See our shadow AI guide.
Watch the sessions
All [Con]nected 2026 sessions are free to watch on the replays page.